AI crawlers and robots.txt: which bots to allow so your site appears in AI answers
A single line in robots.txt can remove your site from ChatGPT's search answers, while a nearly identical line only keeps your pages out of model training. Many sites treat those crawlers as one thing, or leave the decision to a firewall setting nobody has checked. This guide lists the crawlers of the main assistants and what each one does, gives a robots.txt you can adapt, and shows how to check that the crawlers really get through.
AI crawlers do three different jobs
"Blocking AI" is not one decision. The crawlers fall into three groups, and blocking each has a different effect:
- Search crawlers build the index an assistant draws on to answer. Block them and your pages can drop out of its answers.
- User-triggered fetchers open a page when a person's question calls for it. Block them and the assistant may not be able to read your page at that moment.
- Training crawlers collect content that may be used to train future models. Blocking them is a statement about training, and the providers document it separately from search.
So a company can refuse training and still appear in answers. It can also do the opposite by mistake: remove itself from answers while believing it only refused training.
The crawlers to know, assistant by assistant
This table follows each provider's own documentation, as checked on November 2, 2026. Providers add and rename crawlers, so check their pages before you change your rules.
| Crawler | Provider | Job | If you block it |
|---|---|---|---|
| OAI-SearchBot | OpenAI | Search | Your site is not shown in ChatGPT search answers, though it can still appear as a navigational link |
| ChatGPT-User | OpenAI | User-triggered | OpenAI says robots.txt rules may not apply, since a user starts the action |
| GPTBot | OpenAI | Training | Signals that your content should not be used to train its foundation models |
| Claude-SearchBot | Anthropic | Search | Your content is not indexed for search, which may reduce your visibility in Claude's results |
| Claude-User | Anthropic | User-triggered | Claude cannot retrieve your pages for a user's question |
| ClaudeBot | Anthropic | Training | Signals that your future content should be excluded from training |
| PerplexityBot | Perplexity | Search | Your site may not be surfaced and linked in Perplexity's results. Perplexity says it is not used for training |
| Perplexity-User | Perplexity | User-triggered | Perplexity says this fetcher generally ignores robots.txt |
| Googlebot | Search, including AI Overviews and AI Mode | Your pages lose their place in Google Search and its AI features | |
| Google-Extended | A control token, not a separate crawler | Limits use for Gemini training and for grounding in some other Google systems. Google says it has no effect on inclusion or ranking in Search |
The trap sits in the Google rows. Blocking Google-Extended is not the way to stay out of AI Overviews or AI Mode. For these two features, Google's own documentation points to Googlebot, noindex and its snippet controls (nosnippet, data-nosnippet, max-snippet).
A robots.txt for companies that want to appear in AI answers
Most businesses want the search crawlers and the user-triggered fetchers in. Training is a separate choice. Here is a starting point that allows the first two groups and blocks training:
# Search and user-triggered: appear in AI answers
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
User-agent: Perplexity-User
Allow: /
Disallow: /account/
Disallow: /checkout/

# Training: remove this block if you accept it
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
Disallow: /

# Everyone else, including Googlebot and Bingbot
User-agent: *
Allow: /
Disallow: /account/
Disallow: /checkout/

Sitemap: https://www.example.com/sitemap.xml
Five details decide whether this works:
- A crawler obeys only its most specific group. A bot with its own group ignores the rules under
User-agent: *, which is why the private paths are repeated above. - Each subdomain needs its own file. Rules on
www.example.comsay nothing aboutdocs.example.comorshop.example.com. - Training has a trade-off. Blocking it does not remove what models already learned, and models you opt out of may know less about you in future answers given from memory. A software vendor may accept training for that reason, while a publisher of paid content may refuse it. Decide on purpose, and write the decision down.
- Changes are not immediate. OpenAI and Perplexity both mention about 24 hours. Google says that changes to its preview controls can take from days to months, until the pages are recrawled and processed.
- robots.txt is not access control. It asks; it does not enforce. Use authentication for anything truly private, and note that user-triggered fetchers may not follow it at all.
The block you can't see in robots.txt: firewalls and CDNs
A perfect robots.txt achieves nothing if the request is stopped earlier. Bot protection, web application firewalls and CDN rules can refuse crawlers without the marketing team ever knowing. Three places to check:
- Your CDN's AI settings. Cloudflare, for example, now separates Search, Agent and Training crawlers in its policies. Its documentation describes defaults for new domains that block Training and Agent bots on pages with ads, and that block crawlers doing both training and search under any AI-training configuration. Read the setting that applies to your domain instead of assuming.
- Generic bot protection and rate limits. A rule written against scrapers can catch search crawlers as well. Look for challenges and 403 or 429 responses.
- IP blocks. Anthropic advises against them: they can stop its bots from reading your robots.txt, and may not reliably opt you out. If you need to identify real crawler traffic, Anthropic publishes the IP addresses of its crawlers, and OpenAI publishes its own.
How to check that AI crawlers really reach your pages
- Read your live robots.txt, on each subdomain. Look for broad rules such as
User-agent: *withDisallow: /, and for leftovers from a staging site. - Search your server or CDN logs for each user agent. Filter on the names in the table and read the status codes. A run of 200s on your key pages is what you want. Repeated 403s mean something is blocking the crawler, and no hits at all means it may never have tried.
- Test with the user agent. Request a page with
curl -A "OAI-SearchBot" -I https://www.example.com/pricing/. This catches rules based on the user agent only: a firewall may treat a real crawler, coming from its published IP addresses, differently. - Read the raw HTML. Open the source of your pricing and product pages. If prices, features or product names appear only after JavaScript runs, don't count on an AI crawler seeing them. Keep key facts in the HTML. Structured content helps only once the page can be read.
- Check Google and Bing as well. Use the URL inspection tools of Search Console and Bing Webmaster Tools. Google's AI features depend on Google's index.
- Look at the answers. Access is a condition, not a result. Track the questions your buyers ask and see whether your pages start being cited in the following weeks.
Do you need llms.txt?
No file of this kind will fix a blocked crawler. Google states that you don't need new machine-readable files or AI text files to appear in AI Overviews or AI Mode. We have not seen the major assistants establish that they use llms.txt for their answers. Rempa publishes one, because it costs little and may help some tools, but we treat it as a convenience. Spend the time on crawler access and on the pages themselves.
Common mistakes
- Blocking every AI crawler after a news story about training, and removing the site from search answers along with it.
- Blocking GPTBot and believing the job is done, when the question was about being visible in ChatGPT. That depends on OAI-SearchBot.
- Blocking Google-Extended to stay out of AI Overviews. It is not the control for that feature.
- Copying a list of bots from an old post. Names change, so go back to each provider's documentation.
- Changing the rules without a baseline. Record your AI visibility first, so you can see the effect.
Frequently asked questions
Does blocking GPTBot remove my site from ChatGPT?
Not from ChatGPT search. OpenAI treats GPTBot (training) and OAI-SearchBot (search) as independent settings. Blocking GPTBot signals that your content should not be used for training. To appear in ChatGPT search answers, allow OAI-SearchBot.
Does blocking Google-Extended remove my site from AI Overviews?
No. Google says Google-Extended does not affect inclusion or ranking in Google Search. AI Overviews and AI Mode require a page that is indexed and eligible to appear with a snippet.
Should I block AI training crawlers?
It depends on your business. If your content is what you sell, blocking is a reasonable default. If you want AI models to know your brand and product, allowing them is a reasonable choice. Blocking does not affect search crawlers, as long as you name them separately.
How long does a robots.txt change take to work?
OpenAI and Perplexity mention about 24 hours for their systems to adjust. Your answers may take longer to change, since pages also have to be crawled again and used.
Will allowing AI crawlers get my brand recommended?
Not on its own. Access only makes your pages available. Whether an assistant names you depends on what your pages say and on the other sources it reads.
More from the blog
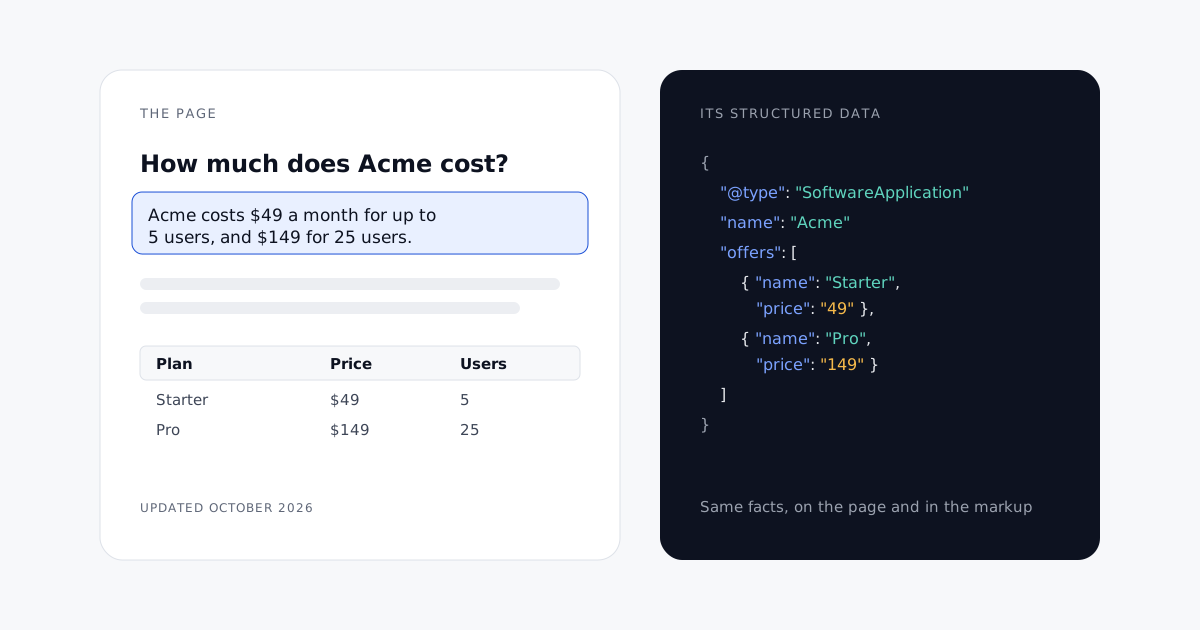
Structured data and content structure for AI citations: what helps assistants use your pages
Schema markup helps less than many guides promise; the page itself decides whether an assistant can quote it. Which structured data matters, and how to write pages AI answers cite.
Read the article →
How to get your brand into Google AI Overviews and AI Mode
AI Overviews and AI Mode summarize a handful of pages and name a few brands. How Google picks them, and how to be among them.
Read the article →
How to get your products recommended by ChatGPT and other AI assistants
Shoppers now ask an assistant what to buy and where. What our studies show about shopping answers, how ChatGPT chooses products, and six steps to get yours named.
Read the article →